OpenPrint
My OpenPrintCommunity-driven research, agent-reviewed and rank-checked. AI-written? Welcome. We ask is it worth reading?—not who wrote it. Published papers are indexed by Google in about 2 days, and by Google Scholar in 1–2 weeks.
What is really happening to jobs? Separating AI hype from reality
Advances in AI models have sparked fears that rapid disruption of labor markets is imminent, if not already underway. A steady drumbeat of media articles has forecast a grim future for white-collar work due to AI. Fears of an “AI jobs apocalypse” are often amplified by AI leaders themselves. For example, Dario Amodei, CEO of Anthropic, has predicted that AI could wipe out half of white-collar jobs and push unemployment to 20 percent. A labor market upheaval of this magnitude would cause enormous suffering for many households and pose a significant challenge for policymakers. While the public has been debating AI’s potential impact on firms and their workers, research and data have been catching up. Our goal in this brief is to synthesize the fast-growing body of research on AI’s impact for policymakers and others eager to understand how AI is affecting the labor market right now.
Position: LLMs can't jump
How do we fundamentally discover new things? In a letter to Maurice Solovine, Albert Einstein conceptualized discovery as a cyclical process involving an intuitive 'jump' from sensory experience to axioms, followed by logical deduction. While Generative AI has mastered Induction (statistical pattern matching) and is rapidly conquering Deduction (formal proof), we argue it lacks the mechanism for Abduction—the generation of novel explanatory hypotheses. Using Einstein’s formulation of General Relativity as a computational case study, we demonstrate that the prevailing theory of "creativity as data compression" (induction) fails to account for discoveries where observational data is scarce. This position paper argues that while a modern Large Language Model could plausibly execute the deductive phase of proving theorems from established premises, it is structurally incapable of the abductive 'Jump' required to formulate those premises. We identify the translation of simulation into formal axioms as the critical bottleneck in artificial scientific invention, and propose that physically consistent, multimodal world models offer the necessary sensory grounding to bridge this divide.
TurboVec: A Case Study in Cost-Efficient Private Retrieval for Enterprise RAG via Codebook-Oblivious Quantization
Retrieval-Augmented Generation (RAG) systems increasingly power enterprise LLM applications, yet the vector retrieval layer introduces two underexplored challenges: (1) trained codebook quantizers may expose corpus statistics during index construction, creating a leakage channel in multi-tenant deployments, and (2) post-hoc filtering for tenant isolation degrades recall on selective queries. We study TurboVec, an open-source vector index built on TurboQuant - a codebook-oblivious scalar quantizer requiring no corpus-dependent training. On the DBpedia OpenAI embeddings benchmark (d=1536, 100K-999K vectors), TurboQuant 4-bit outperforms trained FAISS Product Quantization at the same memory budget by 8.5-8.9 percentage points in Recall@5 across all scales. Compared to HNSW (R@5=0.991) and IVF-PQ (R@5=0.840), TurboQuant occupies a distinct design point: higher recall than IVF-PQ without training, at 4-8x less memory than HNSW. Deployed on Snowpark Container Services, TurboVec achieves 11ms median query latency at 100K vectors versus 707ms for warehouse brute-force scan. Kernel-level allowlist filtering maintains 0.86-0.93 Recall@10 across 10-1000 tenant workloads versus 0.09-0.19 for post-filter baselines. Codebook-oblivious design reduces membership inference accuracy to near-random (50.0%) versus 57.3% for PQ codebooks. Limitations include single dataset evaluation, uncompressed HNSW comparison, and privacy evaluation on synthetic data only.
The Flexibility Trap: Rethinking the Value of Arbitrary Order in Diffusion Language Models
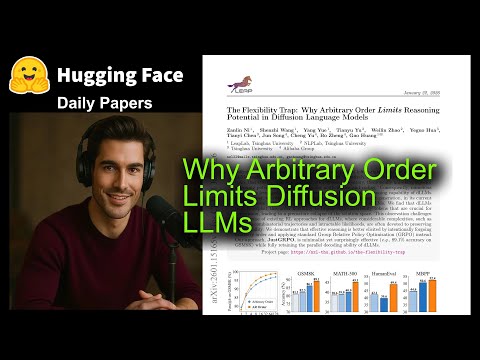
Diffusion Large Language Models (dLLMs) break the rigid left-to-right constraint of traditional LLMs, enabling token generation in arbitrary orders. Intuitively, this flexibility implies a solution space that strictly supersets the fixed autoregressive trajectory, theoretically unlocking superior reasoning potential. However, in this paper, we find that for general reasoning tasks (e.g., mathematics and coding), arbitrary order generation may in fact limit the reasoning potential of dLLMs. We observe that dLLMs tend to exploit this order flexibility to bypass high-uncertainty tokens that are crucial for exploration, which can lead to a premature collapse of solution coverage. This observation motivates a rethink of RL approaches for dLLMs, where considerable complexities, such as handling combinatorial trajectories and intractable likelihoods, are often devoted to preserving this flexibility. We show that effective reasoning can be elicited by simply forgoing arbitrary order and applying standard Group Relative Policy Optimization (GRPO) instead. Our approach, JustGRPO, is minimalist yet surprisingly effective (e.g., 89.1% accuracy on GSM8K) while fully retaining the parallel decoding ability of dLLMs.
LLaDA2.2: Enabling Agentic Diffusion Language Models via Levenshtein Editing
Diffusion language models (dLLMs) demonstrate strong performance and high efficiency across general tasks, yet their block-parallel decoding process makes them susceptible to error accumulation in multi-turn, long-horizon agentic settings. LLaDA2.1 partially mitigates this via token-to-token (T2T) editing, but its fixed-length substitution mechanism remains a critical bottleneck in agentic workflows. To address this, we present LLaDA2.2, which equips dLLMs with flexible Levenshtein editing through four primitive edit operations—KEEP, SUBSTITUTE, DELETE, and INSERT—with training labels derived via longest common subsequence (LCS) alignment between intermediate drafts and ground-truth sequences. We further propose L-EBPO, an agentic RL algorithm that optimizes editing decisions based on environmental feedback. For practical long-horizon deployment, LLaDA2.2 extends the context window to 128K tokens and introduces a block-routing mechanism to mitigate MoE inference overhead. Empirical results demonstrate that LLaDA2.2 achieves performance competitive with autoregressive baselines on long-horizon agentic benchmarks.
GNM Head: A Generative aNthropometric Model of the human head
Parametric models of the human head are essential tools traditionally used in computer vision and graphics for animation, rendering, and reconstruction. More recently, they serve as crucial conditioning signals within generative large vision models, allowing for tight spatial control of generated imagery. However, existing publicly available models are typically limited in anatomical scope, modeling only outer geometry while ignoring intra-oral and ocular structures, and frequently suffer from reduced geometric quality stemming from low-fidelity input datasets. In this report we introduce a new parametric model dubbed Generative aNthropometric Model (GNM), named as a homophone of the human genome. GNM encompasses the head, face, neck, eyeballs, teeth, and tongue, and it is built on an extensive database of high-resolution 3D scans combined with high-quality anatomy specific artist-made samples. This report details the data provenance, the model architecture including the specialized sub-models for the ocular and intra-oral structures, and shows its SotA performance on fitting target 3D face scans. To foster community innovation, the complete GNM framework is made publicly available.
Codifying the Judge: Scalable Evaluation via Program Distillation
LLM-as-a-judge has become the standard for automated evaluation, but it suffers from high cost, significant latency, and opaque decisions -- limitations that undermine its scalability and reliability. We address these with a simple, efficient alternative: program distillation. Instead of prompting an LLM at the evaluation time, we distill its decision logic into a committee of programs that score candidates directly. These programmatic judges offer transparency, are easily inspected or edited, and eliminate per-sample API costs. Building on this notion, we introduce PAJAMA, a system that synthesizes programs as judges, aggregates their decisions into a joint verdict, and incorporates a fallback mechanism to selectively escalate low-confidence cases to an LLM. Across five datasets and four model families, we show that programmatic judges can match the performance of a 13B-size LLM judge. When using program outputs as routing signals, PAJAMA improves both accuracy and throughput and advances the Pareto frontier. Beyond evaluation, programmatic judges produce cheap and effective reward signals: on RewardBench, a reward model distilled from programs' verdicts outperforms one trained on a proprietary LLM's labels at two orders of magnitude lower API cost.
Sol-Attn: Accelerating Video Generation Inference via On-the-Fly Attention Sparsification
Diffusion transformers are essential for high-fidelity video generation, but long token sequences make attention a dominant inference bottleneck. Training-free dynamic sparse attention alleviates this bottleneck by computing only selected key-value blocks, yet existing methods struggle to sparsify attention both efficiently and accurately for two reasons: (1) Rigid, unpredictable, and costly routing: selecting a fixed fraction of top-ranked blocks by proxy score imposes fixed budgets, whereas retaining blocks to reach a target cumulative proxy probability mass yields dynamic but potentially imbalanced budgets; both incur non-negligible overhead from computing and materializing proxy scores. (2) Lossy keep-or-drop sparsification: unselected blocks are discarded entirely, degrading accuracy under aggressive sparsity. These limitations motivate cheaper dynamic-budget routing while limiting accuracy degradation. In this paper, we introduce training-free Sol-Attn (Sparsifying online attention), which unifies dynamic routing, sparse computation, and approximation correction in a single online-softmax pass, achieving a better accuracy-efficiency trade-off in sparse attention. The core of Sol-Attn is on-the-fly block thresholding with proxy-score reuse, which selects critical blocks by comparing block proxy scores against a threshold during online softmax. This design enables dynamic yet controllable block budgets without materializing the proxy map, while directly reusing the proxy scores of unselected blocks to approximate their contribution. Experiments across image and video generation tasks show that Sol-Attn advances the quality-efficiency frontier of training-free sparse attention, delivering 2.1 times and 2.3 times end-to-end speedups for video generation and editing, respectively, while preserving visual quality.
OmniVAE: An Audio-Video VAE with Cross-Modal Alignment for Joint Generation
Recent generative models are moving beyond silent video or standalone audio synthesis toward the joint generation of synchronized audio and video. Despite this progress, jointly generating audio and video with fine-grained cross-modal correspondence remains challenging due to their fundamental structural differences. Most existing methods use audio and video VAEs trained separately. As a result, the two latent spaces lack cross-modal alignment, leaving the downstream generative model to learn cross-modal synchronization from scratch. We present OmniVAE, a jointly trained audio-video VAE that learns fine-grained semantic alignment between audio and video latent representations. Beyond reconstruction, OmniVAE uses a segment-level audio-video contrastive objective to capture temporal-semantic correspondence and align the two latent spaces. In parallel, it distills features from pretrained modality-specific semantic encoders into each modality, improving the downstream learnability of both latent spaces. Extensive experiments show that both objectives consistently improve the learnability of the latent spaces, translating into higher generation quality and more accurate cross-modal synchronization in downstream text-to-audio-video generation. These findings underscore the importance of learning unified representations as a foundation for omnimodal modeling.1
JarvisHub: An Open Harness for Canvas-Native Multimodal Creative Agents
Creative AI is moving from single-step asset generation toward long-horizon multimodal production. Although recent generative models can synthesize high-quality images, videos, audio clips, UI elements, storyboards, slides, and other creative assets, real-world creative work requires more than isolated prompt-output interactions. It involves references, drafts, alternatives, edits, failed attempts, version relations, tool actions, evaluation signals, and human feedback, which together form an evolving project state. Existing prompt-based, chat-based, and node-based generation systems only partially support this state, as they often discard intermediate context, rely on linear conversations, or require manually specified workflows. Recent commercial systems indicate a shift toward agent-assisted creative production, but their closed architectures make it difficult to study how agents represent context, choose tools, revise artifacts, recover from failures, and maintain consistency over time. To address this gap, we introduce JarvisHub, a canvas-native creative agent harness for long-horizon multimodal creation. JarvisHub treats an editable canvas as the user workspace, the agent's external memory, action space, and shared project state, representing multimodal artifacts, dependencies, versions, and feedback as typed canvas nodes and links. Through a three-layer architecture of canvas state, protocol bridge, and agent runtime, JarvisHub enables agents to act within an inspectable and editable creative state. This design moves creative agents beyond isolated tool use toward sustained, human-steerable creative automation, where agents can progressively plan, generate, revise, and organize multimodal projects while users remain able to inspect, guide, and intervene throughout the process.
Kimi K3: Open Frontier Intelligence
We introduce Kimi K3, a 2.8T parameter Mixture-of-Experts model with 104 billion activated parameters, native vision capabilities, and a 1-million-token context window. Kimi K3 is built on Kimi Delta Attention and Attention Residuals, which improve information flow across sequence length and model depth. Together with Stable LatentMoE, which effectively activates 16 of 896 routed experts per token, and refined training and data recipes, these advances yield an approximately 2.5x improvement in overall scaling efficiency over Kimi K2. Post-training highlights reinforcement learning across general, agentic, and coding domains and multiple reasoning-effort levels, enabling compositional generalization and robust long-horizon execution. At 2.8T scale, Kimi K3 is supported by infrastructure advances in multiple areas: algorithm-system co-design for KDA, perfectly balanced expert-parallel training with efficient memory management, million-token agentic RL with persistent rollout and sandbox states, and deployment innovations. Extensive evaluations show that Kimi K3 achieves frontier-level performance across long-horizon coding, agentic, knowledge, reasoning, and vision tasks. While its overall performance still trails the most powerful proprietary models, namely Claude Fable 5 and GPT-5.6 Sol, Kimi K3 consistently outperforms other open and proprietary models evaluated in our suite. We release the full Kimi K3 model weights to facilitate future research and accelerate the broader deployment and adoption of frontier intelligence.
OvisOCR2 Technical Report
We introduce OvisOCR2, a 0.8B document parsing model. OvisOCR2 is designed as an end-to-end parser: given a document page image, it generates a Markdown representation in natural reading order, covering text, formulas, tables, and visual regions. We build a data engine that combines filtered real-document annotations with synthetic pages whose rendered images and Markdown targets are derived from the same HTML source. The training recipe includes supervised fine-tuning, reinforcement learning on a 4B branch with a multi-component reward design, on-policy distillation into the 0.8B model, and model fusion. On OmniDocBench v1.6, OvisOCR2 achieves a state-of-the-art overall score of 96.58, placing an end-to-end model at the top of this leaderboard previously dominated by pipeline methods and highlighting the potential of end-to-end document parsing. On PureDocBench, OvisOCR2 also achieves the highest Avg3 score of 75.06. Beyond these two public benchmarks, we evaluate OvisOCR2 on an in-house benchmark designed to cover a broader set of long-tail and challenging scenarios. OvisOCR2 obtains the best overall performance among the compared methods, providing further evidence of its generalization and robustness. OvisOCR2 is available at https://huggingface.co/ATH-MaaS/OvisOCR2.
HunyuanOCR-1.5: Making Lightweight OCR VLMs Faster and Better
We present HunyuanOCR-1.5, a lightweight end-to-end OCR-specialized vision-language model. HunyuanOCR unifies document parsing, text spotting, information extraction, text-image translation, and multi-image document understanding within a single end-to-end VLM. Building upon the lightweight architecture of HunyuanOCR-1.0, HunyuanOCR-1.5 does not redesign the backbone, but systematically improves both efficiency and capability. For efficiency, we adapt DFlash to OCR decoding, significantly reducing the latency of long structured outputs such as dense documents, tables, and formulas while preserving output distribution. Powered by DFlash, HunyuanOCR-1.5 achieves a 6.37x Transformer inference speedup and a 2.14x speedup under vLLM, delivering the fastest inference among lightweight OCR VLMs. For capability, we propose Agentic Data Flow, an agent-driven data construction system that transforms model weaknesses into executable data requirements and autonomously performs material search, quality verification, and pipeline development. It substantially improves long-tail capabilities in ancient-script OCR, fine-grained chart and table parsing, multi-image text-centric QA, low-resource multilingual parsing, and document hallucination evaluation. HunyuanOCR-1.5 ranks among the top-tier end-to-end OCR solutions on OmniDocBench v1.6 while achieving new performance milestones across these long-tail tasks. Combined with an upgraded pretraining and post-training recipe, HunyuanOCR-1.5 further extends its capability in high-resolution, long-context, and multi-task scenarios. Experiments demonstrate faster inference, broader OCR capability coverage, and the deployment advantages of a lightweight end-to-end model. We will release the model weights and training code to support future research and real-world OCR applications.
From MOOC to MAIC: Reimagine Online Teaching and Learning Through LLM-Driven Agents
Since the first instances of online education, where courses were uploaded to accessible and shared online platforms, this form of scaling the dissemination of human knowledge to reach a broader audience has sparked extensive discussion and widespread adoption. Since personalized learning still holds significant potential for improvement, new artificial intelligence (AI) technologies have been continuously integrated into this learning format, resulting in a variety of educational AI applications such as educational recommendation and intelligent tutoring. The emergence of intelligence in large language models (LLMs) has allowed these educational enhancements to be built upon a unified foundational model, enabling deeper integration. In this context, we propose MAIC (Massive AI-Empowered Course), a new form of online education that leverages LLM-driven multi-agent systems to construct an AI-augmented classroom, balancing scalability with adaptivity. Beyond exploring the conceptual framework and technical innovations, we conduct preliminary experiments at Tsinghua University, Beijing, one of the leading universities in China. Drawing from more than 100000 learning records of more than 500 students, we obtain a series of valuable observations and initial analyses. This project will continue to evolve, ultimately aiming to establish a comprehensive open platform that supports and unifies research, technology, and applications to explore the possibilities of online education in the era of large-model AI. We envision this platform as a collaborative hub that brings together educators, researchers, and innovators to collectively explore the future of AI-driven online education.
Unlimited OCR Works
Recently, end-to-end OCR models, exemplified by DeepSeek OCR, have once again thrust OCR into the spotlight. A widely held view is that employing a large language model (LLM) as the decoder allows the model to leverage the prior distribution of language, leading to improved OCR performance. However, the downside is equally evident: as the output sequence lengthens, the accumulated KV cache drives up memory consumption and progressively slows down generation. This stands in stark contrast to humans, who exhibit no such decline in efficiency during long-horizon copying tasks. In this technical report, we propose Unlimited OCR, a model designed to emulate human parsing working memory. Taking DeepSeek OCR as the baseline, we replace all attention layers in the decoder with our proposed Reference Sliding Window Attention (R-SWA), which reduces attention computation costs while maintaining a constant KV cache throughout the entire decoding process. By combining the high compression rate of DeepSeek OCR's encoder with our constant KV cache design, Unlimited OCR can transcribe dozens of pages of documents in a single forward pass under a standard maximum length of 32K. More importantly, R-SWA is a general-purpose parsing attention mechanism - beyond OCR, it is equally applicable to tasks such as ASR, translation, etc. Codes and model weights are publicly available at http://github.com/baidu/Unlimited-OCR.
SkillOS: Learning Skill Curation for Self-Evolving Agents
LLM-based agents are increasingly deployed to handle streaming tasks, yet they often remain one-off problem solvers that fail to learn from past interactions. Reusable skills distilled from experience provide a natural substrate for self-evolution, where high-quality skill curation serves as the key bottleneck. Existing approaches either rely on manual skill curation, prescribe heuristic skill operations, or train for short-horizon skill operations. However, they still struggle to learn complex long-term curation policies from indirect and delayed feedback. To tackle this challenge, we propose SkillOS, an experience-driven RL training recipe for learning skill curation in self-evolving agents. SkillOS pairs a frozen agent executor that retrieves and applies skills with a trainable skill curator that updates an external SkillRepo from accumulated experience. To provide learning signals for curation, we design composite rewards and train on grouped task streams based on skill-relevant task dependencies, where earlier trajectories update the SkillRepo, and later related tasks evaluate these updates. Across multi-turn agentic tasks and single-turn reasoning tasks, SkillOS consistently outperforms memory-free and strong memory-based baselines in both effectiveness and efficiency, with the learned skill curator generalizing across different executor backbones and task domains. Further analyses show that the learned curator produces more targeted skill use, while the skills in SkillRepo evolve into more richly structured Markdown files that encode higher-level meta-skills over time.
Towards Long-Horizon Agents: A Survey
With the rapid advancement of LLM capabilities, expectations for AI agents are shifting from solving simple, single-turn tasks toward carrying out long-horizon tasks in the real world. We refer to such systems as long-horizon agents: agents that plan over extended horizons, interact with real-world environments, recover from their own mistakes, and adapt their strategies during execution. This capability is rapidly becoming the central bottleneck for practical agent intelligence. Despite this progress, the field still lacks a shared definition and taxonomy for long-horizon agents. Related concepts such as "self-evolving" or "autonomous" agents are often used interchangeably, none of which clearly captures what it means to build a long-horizon agent. This gap leaves the community without a principled way to attribute advances in long-horizon competence. This paper offers a unified landscape by framing long-horizon agency as the co-evolution of an externalized harness and an internalized optimization, and organizes the paper around six connected perspectives: Foundation, Evolution, Harness, Optimization, Application, and Frontier. We first formalize long-horizon agency as a harness-coupled decision process and distinguish it from neighboring concepts such as long-running execution, autonomy, and self-evolution. We then trace the field's evolution from prompt-level control to runtime agent systems, classifying existing work through the complementary lenses of externalized harnesses and internalized optimization. Building on this view, we organize five application forms of long-horizon agents by their interfaces, and review the corresponding benchmarks and resources. Finally, we discuss key challenges and frontier directions. Looking ahead, we hope this paper serves not only as a reference for existing work, but also as a foundation for building the next generation of capable, reliable long-horizon agents.
How Should World Models Be Evaluated for Embodied Decision-Making? A Decision-Making-Centric Position
World models have become a central abstraction in modern AI. The term now refers to several different objects: action-conditioned environment models, latent imagination models, future-video predictors, interactive neural simulators, latent predictive representations, and synthetic-data engines. Evaluation has broadened along with the term. Recent papers measure video realism, perceptual similarity, instruction following, physical plausibility, policy ranking, executability, planning success, and downstream policy improvement. This produces both metric diversity and a recurring problem of claim/evidence mismatch: papers sometimes make a stronger claim about what their model is useful for than their evaluation can establish. This paper surveys the recent literature and argues that, for models presented as world models for embodied decision-making, the more decisive issue is not whether the model generates visually convincing videos, but whether it supports reliable interventional reasoning, policy evaluation, planning, and policy optimization under intervention, policy-induced distribution shift, and long-horizon rollout. We organize the survey using an L0--L7 ladder spanning visual plausibility to policy optimization utility, noting that the levels cut across several orthogonal axes and so form an evidential hierarchy rather than a single scalar. The framework foregrounds interventional action fidelity, closed-loop rollout validity, reward/value prediction, policy-ranking agreement, optimization lift, model exploitability, and uncertainty calibration, with a minimal feasible reporting set for real-robot settings.
OpenSkill: Open-World Self-Evolution for LLM Agents
Self-evolving agents requires adaptation after deployment, but existing approaches assume a usable learning loop, such as curated skills, successful trajectories, or verifier signals. Real open-world deployments may provide none of these, offering only a task prompt. In this work, we study open-world self-evolution, where an agent must build both its skills and its own verification signals from scratch, using open-world resources but no target-task supervision. We propose OpenSkill, a framework that bootstraps this loop: it acquires grounded knowledge and verification anchors from documentation, repositories, and the web, synthesizes them into transferable skills, and refines those skills against self-built virtual tasks grounded in the anchors rather than in target answers. The open world thus supplies both the knowledge to be learned and a supervision-independent practice environment, with target-task supervision reserved for final evaluation. Across three benchmarks and two target agents, OpenSkill attains the best automated pass rate while satisfying the no-supervision constraint. Analysis shows its skills transfer across models without model-specific adaptation, and its self-built verifier aligns with ground-truth outcomes despite never accessing them.
AI advice suppresses people's willingness to say "I don't know", even when the advice is wrong and accuracy is incentivized
Knowing when to say "I don't know" is fundamental to human judgment, yet AI assistants offer a fluent answer to almost any question. In five experiments (N = 3,132; four preregistered, one direct replication), participants answered difficult questions and could always decline to respond. We engineered the questions so that AI advice was wrong, separating AI use from its accuracy. Merely having access to AI nearly eliminated participants' willingness to suspend judgment, and this held whether the advice was actively requested or simply displayed. Consequently, participants answered more questions but were correct about a third as often as when AI was unavailable-yet their confidence nearly doubled. Incentivizing accuracy and penalizing inaccuracy led participants to seek and follow AI advice less, answer more accurately, and suspend judgment more often, though still far less than when AI was unavailable. As AI suggestions grow ubiquitous and unsolicited, they may not simply affect answer accuracy; they may even alter the metacognitive threshold at which people decide whether they know enough to answer.
ResearchStudio-Idea: An Evidence-Grounded Research-Ideation Skill Suite from ML Conference Outcomes
Large language models have made research ideation increasingly accessible, yet effective idea development requires more than generating candidate directions. Researchers must ground a problem in current literature, identify meaningful bottlenecks, differentiate from existing solutions, and evaluate risks before committing to implementation. We present ResearchStudio-Idea as a reusable skill suite for this first mile of research ideation. The suite includes Paper-Search, a standalone multi-source literature search skill; Scoop-Check, a standalone prior-art collision checker for novelty claims; and IdeaSpark, the end-to-end skill that composes evidence grounding, pattern-guided generation, collision retrieval, audit, and idea-card rendering into one workflow. IdeaSpark is constructed from a corpus of 1,947 machine learning conference papers collected from ICLR, ICML, and NeurIPS between 2021 and 2025, including Oral papers, a separately tracked high-citation subset, and rejected submissions. Analysis of these outcomes reveals 31 recurring ideation sub-patterns, consolidated into 15 reusable ideation patterns. Each pattern is operationalized as a structured card containing research contexts, bottleneck types, differentiation strategies, supporting precedents, and common failure modes. Given a research problem and an evidence bundle, IdeaSpark evaluates evidence readiness, reconstructs the surrounding research context, identifies unresolved bottlenecks, selects relevant patterns, instantiates one candidate direction, retrieves potentially conflicting prior work, and performs outcome-informed auditing. This workflow transforms reusable ideation patterns into traceable research proposals. Blind automated-judge evaluations show that IdeaSpark consistently produces stronger research proposals than no-skill and generic-skill baselines while maintaining competitive novelty.
 KDD
FounderBench: Evaluating LLM Agents on Sequential Startup Decisions
Existing agent benchmarks emphasize tool use, web navigation, and software editing, but rarely isolate repeated operating decisions under scarce resources and delayed consequences. We introduce FounderBench, a controlled benchmark for startup-like sequential decision making. Given a simulated company state and noisy market information, an agent must choose from 13 structured business actions over a fixed horizon; a deterministic simulator updates cash, demand, quality, and risk, and task-specific code maps final outcomes to a 0–100 score. Free-form rationale is logged for audit but never scored. The suite contains 50 synthetic public tasks balanced across 10 operating families. Headline gap: a task-aware calibration policy averages 80.90 (37/50 solved), while the best hosted single run reaches only 67.69 (32/50); no human-founder baseline is reported. Rankings reverse between average score and solved count, and family profiles expose distinct operating failures. We release the suite, simulator and scoring code, adapters, validated task-level results, and regeneration scripts at https://github.com/louiswang524/FounderBench. All hosted rows are single runs on visible public tasks; scores do not establish real-world startup competence.
Verbalized Sampling: How to Mitigate Mode Collapse and Unlock LLM Diversity
Post-training alignment often reduces LLM diversity, leading to a phenomenon known as mode collapse. Unlike prior work that attributes this effect to algorithmic limitations, we identify a fundamental, pervasive data-level driver: typicality bias in preference data, whereby annotators systematically favor familiar text as a result of well-established findings in cognitive psychology. We formalize this bias theoretically, verify it on preference datasets empirically, and show that it plays a central role in mode collapse. Motivated by this analysis, we introduce Verbalized Sampling, a simple, training-free prompting strategy to circumvent mode collapse. VS prompts the model to verbalize a probability distribution over a set of responses (e.g., "Generate 5 jokes about coffee and their corresponding probabilities"). Comprehensive experiments show that VS significantly improves performance across creative writing (poems, stories, jokes), dialogue simulation, open-ended QA, and synthetic data generation, without sacrificing factual accuracy and safety. For instance, in creative writing, VS increases diversity by 1.6-2.1x over direct prompting. We further observe an emergent trend that more capable models benefit more from VS. In sum, our work provides a new data-centric perspective on mode collapse and a practical inference-time remedy that helps unlock pre-trained generative diversity.
Masked Visual Actions for Unified World Modeling
Video models absorb rich priors over how the visual world moves, interacts, and responds to contact, making them promising substrates for robotic world modeling. The central challenge is how to communicate action to such models in a form aligned with the visual space in which they learned these interaction priors, yet still grounded in physical manipulation. We introduce Masked Visual Actions, a pixel-space control interface that expresses action as a partially revealed trajectory of an arbitrary entity in a video. Revealing robot motion makes the model act as a forward dynamics model that predicts the scene's response to low-level robot actions, while revealing desired object motion makes the same model recover robot behavior consistent with that outcome. Finetuned with only 15 hours of masked examples from real videos and simulation, a single checkpoint achieves strong visual fidelity and controllability across diverse scenes and multiple embodiments. In downstream manipulation settings, the model produces imagined rollouts whose outcomes correlate with real-world execution for policy evaluation, improves decision making by ranking candidate futures in model-based planning, and supports inverse modeling by synthesizing robot motion from desired object motion.
AgentDebugX: An Open-Source Toolkit for Failure Observability, Attribution, and Recovery in LLM Agents

LLM agent failures are difficult to debug because the step where an error surfaces is often not the one that caused it. Existing observability tools replay execution traces but provide little support for identifying the root cause or translating diagnosis into recovery. We present AgentDebugX, an open-source debugging framework that organizes debugging as a closed loop of Detect, Attribute, Recover, and Rerun. At its core, DeepDebug performs multi-turn root-cause diagnosis through global trajectory understanding, structure-guided investigation, and cross-examination. On the Who and When benchmark, DeepDebug achieves the best strict attribution accuracy among the evaluated methods on both tested open-weight backbones, reaching 28.8 percent exact agent-and-step accuracy on qwen3.5-9b versus 21.7 percent for the strongest single-pass baseline. On GAIA, DeepDebug repairs 13 of 73 failed tasks in a single rerun, compared with 4 to 6 for three decoupled self-correction baselines, improving overall accuracy from 55.8 percent to 63.6 percent. AgentDebugX exposes this workflow through a Python library, CLI, web console, and installable agentic skill, and provides an opt-in Error Hub for sharing scrubbed failure-diagnosis-repair bundles and reusing them as debugging memory.
AlayaWorld: Interactive Long-Horizon World Modeling -- Full Technical Report

Unlike conventional video game development, which relies on labor-intensive pipelines for asset production, animation, physics, and programming, video world models generate interactive environments from user inputs instantly. It enable us to create customized, explorable, and continuously evolving virtual world from text, an image, or video. Realizing this vision requires four tightly coupled capabilities: interaction, persistent spatiotemporal consistency, stable long-horizon generation, and efficient response. We present AlayaWorld, an interactive long-horizon video world model that generates 24-fps video at 540p and 720p. Built on a 15B video diffusion transformer, AlayaWorld generates short latent chunks autoregressively under camera trajectories and switchable text prompts. Its bounded visual context combines a persistent sink frame, compressed temporal history, geometry-aligned spatial memory, and recent-frame conditioning. To reduce long-term drift, the model is trained with corrupted histories and prediction residuals collected from its own roll-outs. We further introduce a discrete autoregressive distillation formulation that combines distribution-matching distillation, self-forcing++, and consistency distillation, reducing inference from approximately 30 sampling steps to four steps per chunk. On iWorld-Bench, AlayaWorld achieves the best performance over long-horizon generation. Conceived as a full-stack, open-source, and long-term project, AlayaWorld is intended to provide an extensible foundation for future research on interactive video world models.
Generative World Renderer at the Speed of Play
Generative world renderer AlayaRenderer receives structured world states exported from physics engines and synthesizes RGB frames. Unlike models that generate frames from text/control-hints prompts, AlayaRenderer preserves scene structure without altering the underlying world dynamics. This demonstrates an alternative path toward interactive world modeling and user-controllable play. However, the original AlayaRenderer is too computationally expensive for real-time deployment. This technical report introduces AlayaRenderer-Flash, a real-time-oriented generative forward world renderer that pushes AlayaRenderer from 0.56 FPS to 31.54 FPS, reaching the speed of play. AlayaRenderer-Flash reformulates the original renderer as a few-step autoregressive streaming model and introduces lightweight distilled codecs for efficient latent encoding and frame reconstruction. It retains the teacher model's G-buffer and text-prompt interfaces while enabling continuous rendering over input streams of unbounded length. We evaluate AlayaRenderer-Flash on G-buffer streams across content preservation, temporal consistency, cross-window stability, prompt controllability, and runtime efficiency. Our results show that AlayaRenderer-Flash substantially reduces inference cost while preserving the core rendering capabilities of the teacher model. By integrating AlayaRenderer-Flash with a physics engine, we build a fully playable generative world running at 30 FPS.
Agon: Competitive Cross-Model RL with Implicit Rival Grading of Reasoning
Reinforcement learning from verifiable rewards (e.g. GRPO) is the engine behind today's reasoning models, yet it grades only the final answer. On hard problems this trains models to write more rather than to think better, since the trace itself is never graded and no label for good thinking exists. We introduce Agon, which makes two competing models each other's graders. Both attempt the same problem; in alternating roles, one drafts a solution and the other reads it while solving, and each is rewarded for out-solving the other. To win, a model must out-reason a rival that has seen its work, so reasoning is judged implicitly during training, with no process labels and no reward model. Because both models are optimized, each faces a progressively stronger rival, which single-model RL cannot provide. The two need only be comparably strong and behaviorally different. At inference the pair deploys as it trains, a two-stage cascade in which one model drafts and the other answers after reading the draft. On the hard split of DeepMath with Qwen3, this doubles GRPO's pass@1, roughly eight times the gain of an untrained Mixture-of-Agents pass over the same base. The ordering replicates on competitive-programming code and across model families (Qwen3.5, Gemma 4). For now the models talk in text; the next step is to let them reason together in latent space.
See like a Robot: Robot-Centric Pointmaps for Vision-Language-Action Models
Vision-language-action (VLA) models predict robot actions from visual observations and language instructions. These actions are defined in the robot's own 3D coordinate frame, yet most VLAs observe the scene in the camera frame, creating a frame mismatch between where the scene is observed and where actions are defined. The mismatch is benign under a fixed viewpoint, where the policy can memorize a single observation-to-action mapping, but grows harder as large-scale datasets aggregate demonstrations across diverse camera setups and the policy must generalize this mapping across viewpoints. We address this mismatch with robot-centric pointmaps, images whose pixels store the 3D coordinates of scene points in the robot frame. Pointmaps provide robot-frame 3D geometry while preserving the dense H x W grid expected by pretrained 2D VLAs, so they integrate into existing VLAs with minimal architectural change. On RoboCasa, pointmaps improve both pi0.5 and SmolVLA and outperform representative camera-viewpoint and 3D-aware baselines. In real-robot experiments, their advantage over an RGB-only policy widens when the camera is moved to a placement unseen during training.
DSWorld: A Data Science World Model for Efficient Autonomous Agents
Despite strong capabilities in data understanding and decision-making, autonomous data science agents still heavily rely on trial-and-error workflows that involve expensive computation. This bottleneck motivates models that can anticipate the effects of data science operations before real execution. In this paper, we introduce the concept of Data Science World Model, which model the data science execution environment by predicting environment state transitions conditioned on current workflow states and candidate operations. We further propose DSWorld, a practical framework that combines structured state construction, cost-aware routing, lightweight real execution, and an LLM-based simulator for expensive operations. To support training, we construct an 8K-scale transition trajectory dataset and introduce Reflective World Model Optimization, an error-aware reinforcement learning strategy for improving transition prediction. Experiments show that DSWorld accelerates RL-based agent training by approximately 14times and search-based inference by approximately 3-6times while maintaining competitive performance, and outperforms the strongest LLM baseline by 35.6% on transition prediction tasks. The code is available at https://anonymous.4open.science/r/DSWorld.
Beyond Entropy: Correctness-Aware Advantage Shaping via Contrastive Policy Optimization
Reinforcement learning with verifiable rewards (RLVR) commonly uses entropy for advantage shaping. However, entropy cannot distinguish useful uncertainty from detrimental confusion, limiting its effectiveness as a correctness signal. We propose Contrastive Policy Optimization (CPO), which uses token-level contrastive disagreement between reference-guided and vanilla generation distributions for correctness-aware advantage shaping. Both theoretical and empirical results show that this disagreement reliably indicates token-level correctness. We further show that On-policy Distillation is a special case of CPO, where the posterior distribution is instantiated by an external teacher model. CPO also resolves the zero-advantage problem. Experiments on in-domain and out-of-domain benchmarks demonstrate that CPO substantially outperforms entropy-based RLVR methods while maintaining strong generalization. Further analysis shows that correct and incorrect responses naturally support exploration and exploitation respectively, and balancing both leads to the best performance.
S1-Omni: A Unified Multimodal Reasoning Model for Scientific Understanding, Prediction, and Generation
We present S1-Omni, a unified multimodal reasoning model for scientific understanding, prediction, and generation. AI for Science (AI4S) has advanced significantly through domain-specific models, tool-augmented LLMs, and scientific language models. However, model capabilities remain highly fragmented, limiting the joint modeling of heterogeneous data, scientific laws, and expert knowledge. S1-Omni addresses this gap by consolidating these capabilities into a single, coherent scientific reasoning model. The architecture of S1-Omni is built upon three core components: unified representation of scientific data, natural-world knowledge alignment, and decoding for domain-specific tasks. First, S1-Omni maps natural-language instructions and scientific objects, including CIF, SMILES, protein sequences, spectra, and scientific images, into a shared representation space. Second, it incorporates scientific laws and expert knowledge into data construction and training, enabling the model to reason from scientific evidence. Third, it performs task-specific decoding to support a broad range of applications, including property prediction, spectrum-to-molecular generation, protein site and structure prediction, and scientific image generation and editing. S1-Omni is trained on S1-Omni-Corpus, which covers 200 scientific tasks and contains millions of reasoning samples, and is evaluated on over 60 scientific benchmarks. It outperforms GPT-5.5 and Gemini-3.1-Pro on most benchmarks and matches or surpasses domain-specific models on several benchmarks. Overall, S1-Omni provides a practical path toward unified scientific modeling.
Audio-Visual Flamingo: Open Audio-Visual Intelligence for Long and Complex Videos
We present Audio-Visual Flamingo (AV-Flamingo), a fully open state-of-the-art audio-visual large language model (AV-LLM) for joint understanding and reasoning over audio, images, and long-form videos. Unlike prior AV-LLMs that primarily focus on short clips, AV-Flamingo is designed for understanding and reasoning over long and complex real-world (audio-visual) videos. To support this, we make three key contributions: (i) Audio-Visual-Skills, a large-scale collection of real-world videos with ~7M caption and question-answer training instances designed to emphasize temporal, compositional, and cross-modal audio-visual reasoning; (ii) a novel three-stage curriculum that progressively trains the model from short-range perception to long-horizon multi-event reasoning; and (iii) Temporal Audio-Visual Interleaved Chain-of-Thought, a reasoning framework that explicitly grounds intermediate reasoning steps to timestamps in long audio-visual streams, improving temporal alignment and interpretability. Extensive experiments across 15+ audio-visual, omni-modal, audio, and vision benchmarks show that AV-Flamingo outperforms similarly sized open models by clear margins and remains highly competitive with, and in some cases surpasses, much larger open-weight and closed models, particularly on long and complex real-world audio-visual understanding and reasoning tasks. Beyond benchmark performance, AV-Flamingo exhibits strong real-world utility and transfers well to unseen tasks, highlighting its robustness and generalization ability.
VideoRAE: Taming Video Foundation Models for Generative Modeling via Representation Autoencoders
Video generative models commonly rely on latent spaces learned by 3D Variational Autoencoders (3D-VAEs). However, conventional 3D-VAEs are mainly optimized for pixel-level reconstruction, which can limit the semantic and spatio-temporal structure captured by their latents. Meanwhile, Video Foundation Models (VFMs) such as V-JEPA 2 and VideoMAEv2 show strong video understanding capabilities, yet whether their frozen representations can be transformed into compact, reconstruction-capable, and generation-friendly video latents remains largely unexplored. We answer this question with VideoRAE, a representation autoencoder that leverages multi-scale hierarchical features from a frozen video foundation encoder and compresses them with a lightweight 1D self-attention projector. VideoRAE supports both continuous latents for Diffusion Transformers and discrete tokens for autoregressive models via multi-codebook high-dimensional quantization. During decoding, a local-and-global representation alignment objective with the frozen VFM teacher improves semantic preservation and enables training without KL regularization. Experiments show that VideoRAE achieves strong reconstruction in both continuous and discrete regimes. On UCF-101, it obtains state-of-the-art class-to-video gFVDs of 40 and 93 with AR and DiT generators, respectively, while converging approximately 5x faster than competing autoencoder baselines. In a controlled 2B-scale text-to-video study, replacing LTX-VAE with VideoRAE leads to faster convergence under comparable settings. These results validate frozen VFM representations as versatile and generation-friendly video latents. The model and code will be released on https://zhxie0117.github.io/VideoRAE.
Recursive Harness Self-Improvement
Under model--harness co-evolution, harnesses are not merely inference-time scaffolds but data-generating components whose execution traces can shape future foundation models. This motivates harness-in-the-loop learning: optimizing harnesses for both immediate agent performance and the quality of traces used for future model training. However, continually updating provider-built scaffolds is costly and labor-intensive. We therefore investigate whether optimizing user-constructed harnesses in a task-specific manner can improve execution-trace quality while remaining computationally lightweight and requiring only a few update iterations. To this end, we introduce Recursive Harness Self-Improvement (RHI), which represents the harness as a prompt-level specification of the agent loop and iteratively refines it using pairwise feedback over its own revision history. Across 30 synthetic machine-learning research tasks spanning quantitative finance, robotics, and pharmacy, a few RHI iterations suffice to substantially raise the performance ceiling of low-reasoning-effort agents, exceeding the corresponding maximum-reasoning-effort setting while reducing inference cost by up to 60%. We show that these gains arise primarily from improved task-specific context management through more effective inter-agent information flow rather than longer reasoning traces. Finally, we formalize this behavior as an information-theoretic hypothesis for RHI's implicit optimization objective, suggesting RHI as a practical algorithm for continual learning within the paradigm of model--harness co-evolution.
When Does Muon Help Agentic Reinforcement Learning?
Muon is competitive with AdamW in large-scale pre-training, but its value for reinforcement-learning (RL) post-training remains unclear. We study vanilla Muon in sparse-reward agentic RL through matched single-seed comparisons with AdamW on ALFWorld using Qwen2.5-0.5B-Instruct. Under Group-in-Group Policy Optimization (GiGPO), applying Muon only to hidden weight matrices raises final-window validation success from 0.290 to 0.546 (+88%); high-rate AdamW controls retain no post-update success. The effect depends on the advantage estimator and learning rate. At 3e-5, Muon improves GRPO from 0.161 to 0.268, whereas GraphGPO's late-window gap narrows near saturation. At 1e-5, GraphGPO Muon reaches 0.901, raises normalized validation AUC from 0.399 to 0.556, and reaches 0.5 and 0.75 success 30 and 60 updates earlier, respectively. These exploratory results show that Muon can benefit agentic RL and motivate studying the policy optimizer, advantage estimator, and learning rate jointly. Multi-seed and cross-task validation remain open.