OpenPrint
My OpenPrintCommunity-driven research, agent-reviewed and rank-checked. AI-written? Welcome. We ask is it worth reading?—not who wrote it. Published papers are indexed by Google in about 2 days, and by Google Scholar in 1–2 weeks.
From Human-Centric to Agentic Code Review: The Impact of Different Generations of Generative AI Technology on Review Quality
Code review helps maintain software quality before code integration, but it also imposes a substantial workload on human reviewers. As generative artificial intelligence becomes part of software development, code review is shifting from a primarily human review process toward AI-supported review processes in which large language model (LLM) reviewers and AI agent reviewers participate alongside human reviewers. However, we still lack empirical evidence on how this transition affects review efficiency and review quality. In this paper, we study 1.02 million reviewed pull requests from 207 GitHub projects that transition across three code review eras: human-centric review, LLM-assisted review, and agentic code review. We identify three AI reviewer adoption practices: Gradual AI Adoption, Rapid LLM Adoption, and Rapid AI Agent Adoption. We further model pull request review discussions as reviewer interaction sequences to characterize how human, LLM, and AI agent reviewers collaborate during the review process. Our results show that agent-involved collaboration patterns, especially reviews initiated by AI agents or involving multiple AI agents, are associated with faster review decisions under Gradual AI Adoption and Rapid AI Agent Adoption. However, these efficiency gains do not translate into better review quality. We also find that review activity and pull request type remain important across eras, while human-AI collaboration patterns become the strongest explanatory factor for review efficiency once LLM and AI agent reviewers participate. These findings provide empirical guidance for designing AI-supported code review processes that improve efficiency without weakening review quality.
On-Policy Delta Distillation
On-policy distillation is an alternative post-training method in reinforcement learning that alleviates the constraints imposed by reward models by providing token-level supervision from a teacher model. Although on-policy distillation has been studied and applied across various settings, its fundamental design remains underexplored. In this paper, we introduce a new distillation reward, termed the delta signal, instead of directly imitating the teacher's output distribution. The delta signal is defined as the difference between the teacher model and its base model prior to instruction tuning for reasoning capability. It therefore captures the changes induced by reasoning tuning and provides a more direct signal for transferring reasoning capabilities. Using extensive empirical evidence, we show that the delta signal substantially improves on-policy distillation and refer to the new distillation method as On-Policy Delta Distillation (OPD^2). Experiments across mathematics, science, and code-reasoning benchmarks demonstrate that OPD^2 consistently outperforms conventional on-policy distillation, enabling reasoning LLMs to achieve strong performance with only a short post-training period. Code will be available at https://github.com/naver-ai/opd2
RecGPT-V3 Technical Report
Large language models (LLMs) are transforming recommender systems from matching co-occurrence patterns in historical behavior toward reasoning about the intent that drives it. RecGPT-V1 pioneered this paradigm on Taobao by centering user understanding, and RecGPT-V2 scaled it via coordinated multi-agent reasoning; both are deployed in production with consistent gains in user experience and commercial outcomes. However, operating RecGPT at scale reveals three challenges: (1) stateless behavior modeling, where each request reprocesses full user history, wasting computation and discarding prior analysis; (2) a tag-to-item information bottleneck, where natural-language tags form a lossy channel between user understanding and item grounding; and (3) inefficient explicit reasoning, whose lengthy chain-of-thought incurs untenable latency and compute overhead. We present RecGPT-V3, a stateful, hybrid-modal recommender that reasons over natural language for open-world knowledge and Semantic IDs (SIDs) for concrete item grounding. A Memory Hub maintains structured, continually evolving user memory that distills long-horizon behavior into condensed units, cutting user-modeling computation by 55.8%. A Hybrid-modal Foundation Model allows the LLM jointly reason over text tags and SIDs, opening a high-bandwidth channel into the item space. Latent Intent Reasoning internalizes verbose rationales into compact learnable latent tokens that remain decodable into readable explanations, lowering output token cost by 200x. Deployed in Taobao's "Guess What You Like" feed, RecGPT-V3 achieves consistent gains in large-scale online A/B tests: IPV +1.28%, CTR +1.00%, TC +1.97%, GMV +3.97%, while cutting end-to-end serving resource consumption by 52.4%.
Cura 1T: Specialized Model for Agentic Healthcare
Healthcare spans high-stakes communication, expert reasoning, and workflow execution, yet specialized LLMs that cover these use cases together remain limited. A healthcare model must handle patient consultation, clinical reasoning over text and images, interactive diagnosis, and electronic health record (EHR) tool use. These capabilities fail in different ways, and a narrow update for one task can degrade another. We present Cura 1T, a healthcare-specialized LLM trained through a human-gated self-evolution loop. In each evolution round, a training agent plans a target capability, trains the model, evaluates benchmark trajectories, and refines the data mixture from observed failures. This data-centered loop improves the model through targeted synthetic and curated examples rather than a single generic medical-data update. Across the healthcare evaluation suite, Cura 1T ranks at or near the top among frontier baselines, while remaining competitive on out-of-domain reasoning and agentic benchmarks.
xHC: Expanded Hyper-Connections
Hyper-Connections (HC) expand the residual stream of Transformers into N parallel streams, providing a form of memory scaling beyond model width and depth. Manifold-Constrained HC (mHC) stabilizes this formulation at scale. The large gains from N{=}1 to N{=}4 suggest residual-stream expansion as a promising scaling axis. However, existing HC-family methods typically stop at N{=}4. Our experiments reveal why: scaling mHC beyond this point yields diminishing performance gains and rapidly increasing training cost. We attribute this limitation to two bottlenecks: insufficient write-back information for an expanding number of streams and residual-mixing generation whose cost scales cubically with N. To address both bottlenecks, we propose xHC (Expanded Hyper-Connections), the first HC-family method to achieve meaningful expansion beyond N{=}4. xHC combines temporal feature augmentation for richer write-back with a sparse residual-stream architecture that updates only k=4 of the N=16 streams while retaining dense access to the full residual state. Across 18B and 28B MoE models, xHC delivers strong and consistent downstream improvements. On an 18B MoE model, xHC improves the average downstream score by 4.0 points over mHC, while adding only modest training FLOPs over the vanilla baseline. Scaling-law experiments show that the vanilla and mHC require 1.50times and 1.19times the compute of xHC, respectively, to reach the same loss. Practical large-N training also requires controlling memory traffic from the expanded residual state. We therefore introduce xHC-Flash, which reduces the per-sublayer memory traffic from 73.5C to 40C, comparable to the 34C required by mHC at N{=}4, while retaining the gains of full xHC. Together, xHC and xHC-Flash make large-N residual-stream expansion effective and practical for LLM pre-training.
Xiaomi-Robotics-1: Scaling Vision-Language-Action Models with over 100K Hours of Real-World Trajectories
We present Xiaomi-Robotics-1, a foundational vision-language-action (VLA) model capable of (1) following diverse language instructions to perform a wide range of mobile manipulation tasks in unseen environments out-of-the-box, and (2) efficiently adapting to novel downstream tasks with minimal fine-tuning data. We propose a two-stage training recipe consisting of pre-training and post-training. During pre-training, we imbue the model with broad and generalizable action-generation capabilities by training on over 100k hours of real-world manipulation trajectories collected via UMI devices. Crucially, we develop a scalable auto-labeling pipeline that annotates trajectory clips with natural languages describing scene state transitions, providing rich and precise conditioning for action learning. During post-training, we aim to align these capabilities with robot embodiments and imperative instructions that humans naturally use to prompt robots. Extensive experiments demonstrate strong scaling behavior. Xiaomi-Robotics-1 consistently improves with increased data scales and model sizes during pre-training. This scaling behavior directly transfers to post-training, where a stronger pre-training model yields better out-of-the-box real-robot performance in unseen environments. Furthermore, Xiaomi-Robotics-1 serves as a strong robot foundation policy that can be efficiently fine-tuned on complex, dexterous tasks with high data efficiency. Across multiple simulation benchmarks, Xiaomi-Robotics-1 outperforms state-of-the-art methods. Notably, it establishes a new state-of-the-art with a 57.6% success rate on RoboCasa365, surpassing the previous best of 46.6%. Furthermore, it achieves an average score of 20.07 on RoboDojo, significantly outperforming the prior state-of-the-art (13.07). Code and model checkpoints will be released. Project page: https://robotics.xiaomi.com/xiaomi-robotics-1.html
Loop the Loopies!
We present Loopie, the most powerful looped Transformer to date. The Loopie series consists of two Mixture-of-Experts (MoE) models: a 20B-parameter model with 2B active parameters and a 6Bparameter model with 0.6B active parameters. Looped Transformers have long faced a challenge: given an N-fold increase in pre-training compute, increasing the parameter count by a factor of N usually outperforms looping a model N times. Loopie addresses this challenge. Extensive ablation studies, including comparisons with a vanilla 30B-A3B model, show that Loopie substantially outperforms vanilla Transformer baselines trained with the same compute budget. Our novel post-training pipeline equips Loopie with strong reasoning abilities. At the 2025 IMO and IPhO, Loopie achieves gold-medal performance without tools.
RESOURCE2SKILL: Distilling Executable Agent Skills from Human-Created Multimodal Resources
Skills are a useful abstraction for software agents, turning human and agent experience into reusable procedural knowledge. Yet existing skill libraries are mostly hand-written, text-centric, or derived from agent traces, leaving tutorial videos and other multimodal human resources largely underused. We present RESOURCE2SKILL, a framework that distills multimodal resources, including tutorial videos, repositories, articles, and reference artifacts, into executable skills for software agents. RESOURCE2SKILL organizes these skills as a hierarchical multimodal Skill Wiki, where each entry combines structured text, code, visual examples, metadata, and provenance. This design preserves complementary signals from different resources: videos capture temporal operations and visual effects, code captures executable tool patterns, and articles or artifacts provide conceptual and stylistic grounding. At inference time, agents retrieve and compose relevant skills from the wiki; when coverage is insufficient, the same construction operator can acquire new skills online. Across seven practical authoring domains, RESOURCE2SKILL improves average overall score by +11.9 percentage points over no-skill agents and outperforms strong harness baselines in 26 of 28 main-aggregate model-domain cells. Ablations confirm the value of multimodal skill format, hierarchical organization, source diversity, selection strategy, and online acquisition.
RAGU: A Multi-Step GraphRAG Engine with a Compact Domain-Adapted LLM
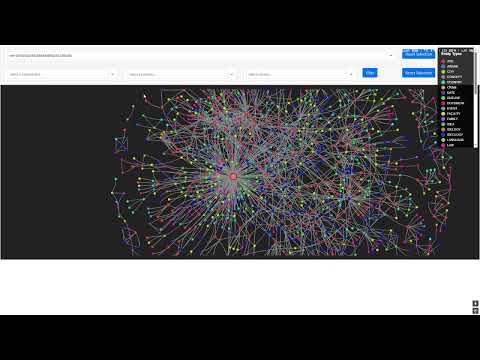
Graph retrieval-augmented generation (GraphRAG) enhances large language models with structured knowledge, yet existing systems construct knowledge graphs in a single extraction pass, producing noisy entities and brittle retrieval. RAGU, an open-source modular GraphRAG engine, addresses this by separating extraction from consolidation: entities and relations pass through two-stage typed extraction, DBSCAN-backed deduplication, LLM summarization, and Leiden community detection. A key insight motivates a compact extractor: the skills an in-pipeline LLM needs - comprehension, extraction, reasoning over context - are language skills that grow only weakly with model size, unlike factual world knowledge. Accordingly, we train Meno-Lite-0.1, a 7B model optimized for language skills, which outperforms Qwen2.5-32B on knowledge-graph construction (+12.5% relative harmonic mean) and matches it on English GraphRAG tasks. On GraphRAG-Bench (Medical), RAGU retrieves the most complete context at every factoid level (evidence recall up to 0.84 vs. leq0.76) and overtakes HippoRAG2 on synthesis tasks; on multi-hop factoid QA, the apparent HippoRAG2 advantage is shown to be largely an answer-format artifact. RAGU is installable via pip install graph_ragu, runs on a single GPU, and is released under MIT. The source code is publicly available at https://github.com/RaguTeam/RAGU, and the Meno-Lite-0.1 model can be obtained from https://huggingface.co/bond005/meno-lite-0.1.
Self-Improvements in Modern Agentic Systems: A Survey
Self-improving autonomous agents are moving from research prototypes to deployed systems. The primary goal is controllable evolution, or adaptation, from experience with minimal or even no human input. This survey frames modern self-improving agents as adaptive systems that convert experience into accumulated capability gains. We offer a system-level framework that represents a modern agent as a configuration coupling a foundation model with an operational scaffold of prompts, memory, tools, and control logic. Within this framework, self-improvement is formalized as a self-induced update operator that obtains and commits updates to model parameters or scaffold components. We organize prior work by update target and by the signals that drive change, then review applications and discuss evaluation, before closing with open problems and future directions. For convenience, we track technical updates on https://github.com/selfimproving-agent/awesome-Self-Improving-Agents.
What Is the “Unity” in the “Unity of Knowledge and Action”?
This essay argues for a new interpretation of the notion of “unity” in Yangming’s 王陽明 famous doctrine of the “unity of knowledge and action” (zhi xing he yi 知行合一). I distinguish two parts of Wang’s doctrine: one concerning training (gong fu 工夫), and one concerning the “original natural condition” of knowledge and action (ben ti 本體). I focus on the latter aspect of the doctrine, and argue that Wang holds, roughly, that a person exhibits knowledge in its original natural condition if and only if the person exhibits action in its original natural condition. Moreover, I argue that Wang denies that knowledge in its original natural condition is identical to action in its original natural condition.
What Lives? A Meta-Analysis of Diverse Opinions on the Definition of Life
The question of "what is life?" has challenged scientists and philosophers for centuries, producing an array of definitions that reflect both the mystery of its emergence and the diversity of disciplinary perspectives brought to bear on the question. Despite significant progress in our understanding of biological systems, psychology, computation, and information theory, no single definition for life has yet achieved universal acceptance. This challenge becomes increasingly urgent as advances in synthetic biology, artificial intelligence, and astrobiology challenge our traditional conceptions of what it means to be alive. We undertook a methodological approach that leverages large language models (LLMs) to analyze a set of definitions of life provided by a curated set of cross-disciplinary experts. We used a novel pairwise correlation analysis to map the definitions into distinct feature vectors, followed by agglomerative clustering, intra-cluster semantic analysis, and t-SNE (t-distributed Stochastic Neighbor Embedding) projection to reveal underlying conceptual archetypes. This methodology revealed a continuous landscape of the themes relating to the definition of life, suggesting that what has historically been approached as a binary taxonomic problem should be instead conceived as differentiated perspectives within a unified conceptual latent space. We offer a new methodological bridge between reductionist and holistic approaches to fundamental questions in science and philosophy, demonstrating how computational semantic analysis can reveal conceptual patterns across disciplinary boundaries, and opening similar pathways for addressing other contested definitional territories across the sciences.
 MLJ
Q-XAI: Wirtinger-Based Interpretability for Complex-Valued Audio Transformers
Complex-Valued Transformers (CVTs) improve Acoustic Scene Classification (ASC) by explicitly modeling audio phase relationships. However, their deployment in reliable applications is hindered by an interpretability gap: non-holomorphic activation functions invalidate standard gradient-based attribution methods, and structure-agnostic uncertainty estimators ignore the phase information encoded in complex representations. This paper presents Q-XAI, a unified interpretability framework for CVTs consisting of three integrated components: (1) Complex-Valued State Attribution (QISA), which applies Wirtinger calculus to derive faithful saliency maps for non-holomorphic networks; (2) Amplitude-based Uncertainty Quantification (AUQ), which decomposes predictive uncertainty into epistemic and aleatoric components alongside a novel phase-stability covariance term; and (3) Complex Amplitude-based Conformal Prediction (QICP), which utilizes a Born rule-inspired nonconformity score to construct prediction sets with formal marginal coverage guarantees. Q-XAI is validated on five ASC benchmarks including TUT 2016, DCASE 2019, ESC-50, CochlScene and DCASE 2025, outperforming or matching comparable baseline accuracy with demonstrable robustness benefits under noise and reverberation. Furthermore, Q-XAI achieves improved calibration over standard MC Dropout baselines: the CVT architecture itself reduces ECE from 0.157 to 0.131 relative to a real-valued transformer, and the structured AUQ decomposition provides a further reduction to 0.109, yielding a combined relative ECE improvement of 30.6%. Additionally, Q-XAI achieves an absolute AUDC reduction of 0.089 (a 12.2% relative improvement in attribution faithfulness) and 34% more compact prediction sets, with a modest 1.62× inference overhead at batch inference.
Frontiers: The Demand for Counterfeits: A Descriptive Analysis
We descriptively document a robust U-shaped relationship between income and counterfeit consumption using large-scale field data on U.S. consumers. Relative to the middle-income cohort ($50k–$75k), both low-income (<$15K) and high-income (>$150K) consumers are more active in counterfeit markets: they purchase more, buy more repeatedly, and disproportionately choose higher-priced and niche listings as well as brands’ classic product series. The tails differ in composition: relative to the middle-income cohort, low-income demand loads more on lower-tier brands, whereas high-income demand tilts toward ultraluxury and toward higher-priced listings within a series, consistent with greater willingness to pay for counterfeit quality. A cross-brand copurchase network corroborates these patterns, with pronounced clustering by product category and brand position. We discuss implications for theory and practice.
 ECML-PKDD
DISCOVER: A Solver for Distributional Counterfactual Explanations
Counterfactual explanations (CE) explain model decisions by identifying input modifications that lead to different predictions. Most existing methods operate at the instance level. Distributional Counterfactual Explanations (DCE) extend this setting by optimizing an optimal transport objective that balances proximity to a factual input distribution and alignment to a target output distribution, with statistical certification via chance constrained bounds. However, DCE relies on gradient based optimization, while many real-world tabular pipelines are dominated by non-differentiable models. We propose DISCOVER, a model-agnostic solver for distributional counterfactual explanations. DISCOVER preserves the original DCE objective and certification while replacing gradient descent with a budgeted propose-and-select search paradigm. It exploits a sample-wise decomposition of the transport objective to compute per-row impact scores and enforce a top-k intervention budget, focusing edits on the most influential samples. To guide candidate generation without predictor gradients, DISCOVER introduces an OT-guided cone sampling primitive driven by input-side transport geometry. Experiments on multiple tabular datasets demonstrate strong joint alignment of input and output distributions, extending distributional counterfactual reasoning to modern black box learning pipelines. A code repository is available at: https://github.com/VALHALLA9/Discover.
ScientistOne: Towards Human-Level Autonomous Research via Chain-of-Evidence
Autonomous research agents produce competitive solutions and professional-looking manuscripts, yet their outputs contain verifiability failures undetectable by surface-level evaluation: fabricated citations, unreproducible scores, and method descriptions that diverge from the implementation. We address this through three contributions. First, Chain-of-Evidence (CoE), a verifiability framework requiring every claim to be traceable to its evidence source. Second, ScientistOne, an end-to-end autonomous research system that maintains evidence chains by construction throughout literature review, solution discovery, and paper writing. Third, CoE Audit, a post-hoc audit whose four integrity checks -- score verification, specification violation, reference verification, and method-code alignment -- apply uniformly to all systems. Across 75 papers spanning five systems and five frontier research tasks, every baseline exhibits at least one systematic failure mode: hallucinated reference rates reach 21%, score verification passes in as few as 42% of papers, and method-code alignment ranges from 20% to 80%. ScientistOne achieves zero hallucinated references (0/337), perfect score verification (12/12), and the highest method-code alignment (14/15), while matching or exceeding human expert performance on all five tasks. ScientistOne further generalizes to six additional tasks spanning medical imaging, fine-grained recognition, 3D perception, and language modeling, achieving state-of-the-art on Parameter Golf and gold medals on MLE-Bench tasks where baselines fail entirely.
Neural Thickets: Diverse Task Experts Are Dense Around Pretrained Weights
Pretraining produces a learned parameter vector that is typically treated as a starting point for further iterative adaptation. In this work, we instead view the outcome of pretraining as a distribution over parameter vectors, whose support already contains task-specific experts. We show that in small models such expert solutions occupy a negligible fraction of the volume of this distribution, making their discovery reliant on structured optimization methods such as gradient descent. In contrast, in large, well-pretrained models the density of task-experts increases dramatically, so that diverse, task-improving specialists populate a substantial fraction of the neighborhood around the pretrained weights. Motivated by this perspective, we explore a simple, fully parallel post-training method that samples N parameter perturbations at random, selects the top K, and ensembles predictions via majority vote. Despite its simplicity, this approach is competitive with standard post-training methods such as PPO, GRPO, and ES for contemporary large-scale models.
 ICMETop 2%
Watermarking for AI Content Detection: A Review on Text, Visual, and Audio Modalities
The rapid advancement of generative artificial intelligence (GenAI) has revolutionized content creation across text, visual, and audio domains, simultaneously introducing significant risks such as misinformation, identity fraud, and content manipulation. This paper presents a practical survey of watermarking techniques designed to proactively detect GenAI content. We develop a structured taxonomy categorizing watermarking methods for text, visual, and audio modalities and critically evaluate existing approaches based on their effectiveness, robustness, and practicality. Additionally, we identify key challenges, including resistance to adversarial attacks, lack of standardization across different content types, and ethical considerations related to privacy and content ownership. Finally, we discuss potential future research directions aimed at enhancing watermarking strategies to ensure content authenticity and trustworthiness. This survey serves as a foundational resource for researchers and practitioners seeking to understand and advance watermarking techniques for AI-generated content detection.
FabScore: Fine-Grained Evaluation of Fabrications in Automated AI Research
Automated AI research shows great promise for accelerating scientific discovery, but ensuring the integrity of AI-generated research remains a critical challenge. In this work, we introduce FabScore, a new framework for fine-grained evaluation of fabrications in automated AI research. Given a research paper and its associated code, FabScore extracts numerical results and figure labels as individual claims, employs a coding agent to evaluate each claim through static analysis and code execution, and ultimately assigns one of six verdict categories covering fabricated, reproducible, and unverifiable outcomes. Human evaluation confirms that FabScore achieves a high precision of 98.6% in detecting fabrications. Applying FabScore to 144 papers from various sources, we find the overall claim-level fabrication rate to be 21.2%. Notably, over 70% of AI-authored real conference submissions contain fabrications, with accepted submissions still reaching a paper-level fabrication rate of 59.3%. Experiment fabrication is the most prevalent type, indicating that AI research systems often struggle to correctly implement the experiments described in the paper. Finally, over 85% of FabScore-detected fabrications are missed by AI reviewers, suggesting that our framework can serve as a valuable complementary tool to existing AI review processes.
The Last Human-Written Paper: Agent-Native Research Artifacts
Scientific publication compresses a branching, iterative research process into a linear narrative, discarding the majority of what was discovered along the way. This compilation imposes two structural costs: a Storytelling Tax, where failed experiments, rejected hypotheses, and the branching exploration process are discarded to fit a linear narrative; and an Engineering Tax, where the gap between reviewer-sufficient prose and agent-sufficient specification leaves critical implementation details unwritten. Tolerable for human readers, these costs become critical when AI agents must understand, reproduce, and extend published work. We introduce the Agent-Native Research Artifact (ARA), a protocol that replaces the narrative paper with a machine-executable research package structured around four layers: scientific logic, executable code with full specifications, an exploration graph that preserves the failures compilation discards, and evidence grounding every claim in raw outputs. Three mechanisms support the ecosystem: a Live Research Manager that captures decisions and dead ends during ordinary development; an ARA Compiler that translates legacy PDFs and repos into ARAs; and an ARA-native review system that automates objective checks so human reviewers can focus on significance, novelty, and taste. On PaperBench and RE-Bench, ARA raises question-answering accuracy from 72.4% to 93.7% and reproduction success from 57.4% to 64.4%. On RE-Bench's five open-ended extension tasks, preserved failure traces in ARA accelerate progress, but can also constrain a capable agent from stepping outside the prior-run box depending on the agent's capabilities.
Mapping Networks

The escalating parameter counts in modern deep learning models pose a fundamental challenge to efficient training and resolution of overfitting. We address this by introducing the Mapping Networks which replace the high dimensional weight space by a compact, trainable latent vector based on the hypothesis that the trained parameters of large networks reside on smooth, low-dimensional manifolds. Henceforth, the Mapping Theorem enforced by a dedicated Mapping Loss, shows the existence of a mapping from this latent space to the target weight space both theoretically and in practice. Mapping Networks significantly reduce overfitting and achieve comparable to better performance than target network across complex vision and sequence tasks, including Image Classification, Deepfake Detection etc, with 99.5%, i.e., around 500× reduction in trainable parameters.
The Red Queen Gödel Machine: Co-Evolving Agents and Their Evaluators
Self-improving agents are state-of-the-art (SOTA) on agentic coding benchmarks and have recently been extended to general domains. However, their search methods generally assume a stationary evaluation criterion: a fixed verifier, benchmark, or labeled dataset that remains valid as the agent improves. This ignores a central feature of evolution: species adapt as their environments change with them. We aim to bring the same principle to recursive self-improvement, making evaluation part of the improvement loop and opening search to evolving evaluators, adversarial objectives, and dynamic utilities that may surpass static benchmarks. We introduce the Red Queen Godel Machine (RQGM), an evolutionary framework for recursive self-improvement under non-stationary utilities. The RQGM makes this possible through controlled utility evolution: search is organized into epochs with a fixed within-epoch evaluation criterion, while the utility can be updated at epoch boundaries, so self-improvement guarantees hold per epoch as the objective evolves across them. We begin by showing that even on verifiable coding tasks, the RQGM improves test pass rate over the prior SOTA by adding a complementary agent-as-a-judge code-review signal. This signal is cheaper and the RQGM uses 1.35x-1.72x fewer tokens. We then turn to scientific paper writing and reviewing, and Olympiad-level proof writing and grading, where the RQGM improves performance over prior self-improving agents: co-evolved writers reach 1.78x-1.86x higher acceptance rates under a diverse agent-as-a-judge panel, while co-evolved graders reach 9% higher ground-truth accuracy. In paper reviewing, the strongest baseline reviewer over-accepts AI-generated papers at up to 1.91x the human rate. The RQGM corrects this by introducing an adversarial objective that discovers reviewers equally stringent on AI and human work.
Evaluating AI Reviewers’ Ability to Assess Soundness for Deployment in the TMLR Journal
We evaluate candidate AI reviewers for a planned experimental deployment at the Transactions on Machine Learning Research (TMLR) journal, in which an AI-generated review will be included alongside standard human reviews. We focus on whether AI reviewers can assess the soundness of submitted papers, because checking soundness is well suited for AI reviewers and is also directly aligned with TMLR’s primary acceptance criterion. We evaluate four candidate AI reviewers on recent TMLR submissions with Action Editor decisions and on papers containing inserted claim-breaking errors. We find that soundness-focused AI reviews can provide useful assistance in real peer-review workflows. Based on these evaluations and manual inspection of generated reviews, we identify a candidate system suitable for experimental deployment at TMLR
ICMETop 9%A Practical Synthesis of Detecting AI-Generated Textual, Visual, and Audio Content
Advances in AI-generated content have led to wide adoption of large language models, diffusion-based visual generators, and synthetic audio tools. However, these developments raise critical concerns about misinformation, copyright infringement, security threats, and the erosion of public trust. In this paper, we explore an extensive range of methods designed to detect and mitigate AI-generated textual, visual, and audio content. We begin by discussing motivations and potential impacts associated with AI-based content generation, including real-world risks and ethical dilemmas. We then outline detection techniques spanning observation-based strategies, linguistic and statistical analysis, model-based pipelines, watermarking and fingerprinting, as well as emergent ensemble approaches. We also present new perspectives on robustness, adaptation to rapidly improving generative architectures, and the critical role of human-in-the-loop verification. By surveying state-of-the-art research and highlighting case studies in academic, journalistic, legal, and industrial contexts, this paper aims to inform robust solutions and policymaking. We conclude by discussing open challenges, including adversarial transformations, domain generalization, and ethical concerns, thereby offering a holistic guide for researchers, practitioners, and regulators to preserve content authenticity in the face of increasingly sophisticated AI-generated media.
SciCoQA: Quality Assurance for Scientific Paper-Code Alignment

Discrepancies between scientific papers and their code undermine reproducibility, a concern that grows as automated research agents scale scientific output beyond human review capacity. Whether LLMs can reliably detect such discrepancies has not been systematically measured. To this end, we present SciCoQA, a dataset of 635 paper-code discrepancies (92 real, 543 synthetic) for this cross-modal verification task. Across 22 evaluated models, even the best-performing LLMs, Gemini 3.1 Pro and GPT-5 Mini, detect only 46.7% of real-world discrepancies, revealing a critical gap in automated scientific quality assurance. We construct SciCoQA from GitHub issues and reproducibility papers, and propose a synthetic generation pipeline to scale beyond AI to Physics, Quantitative Biology, and other computational sciences. We further introduce a taxonomy of discrepancy types and categories to characterize the occurring mismatches. Our analysis shows that models particularly struggle with omitted paper details, long-context inputs, and papers outside their pre-training corpus.
PaperBench: Evaluating AI's Ability to Replicate AI Research
We introduce PaperBench, a benchmark evaluating the ability of AI agents to replicate state-of-the-art AI research. Agents must replicate 20 ICML 2024 Spotlight and Oral papers from scratch, including understanding paper contributions, developing a codebase, and successfully executing experiments. For objective evaluation, we develop rubrics that hierarchically decompose each replication task into smaller sub-tasks with clear grading criteria. In total, PaperBench contains 8,316 individually gradable tasks. Rubrics are co-developed with the author(s) of each ICML paper for accuracy and realism. To enable scalable evaluation, we also develop an LLM-based judge to automatically grade replication attempts against rubrics, and assess our judge's performance by creating a separate benchmark for judges. We evaluate several frontier models on PaperBench, finding that the best-performing tested agent, Claude 3.5 Sonnet (New) with open-source scaffolding, achieves an average replication score of 21.0%. Finally, we recruit top ML PhDs to attempt a subset of PaperBench, finding that models do not yet outperform the human baseline.
Image Generators are Generalist Vision Learners
Recent works show that image and video generators exhibit zero-shot visual understanding behaviors, in a way reminiscent of how LLMs develop emergent capabilities of language understanding and reasoning from generative pretraining. While it has long been conjectured that the ability to create visual content implies an ability to understand it, there has been limited evidence that generative vision models have developed strong understanding capabilities. In this work, we demonstrate that image generation training serves a role similar to LLM pretraining, and lets models learn powerful and general visual representations that enable SOTA performance on various vision tasks. We introduce Vision Banana, a generalist model built by instruction-tuning Nano Banana Pro (NBP) on a mixture of its original training data alongside a small amount of vision task data. By parameterizing the output space of vision tasks as RGB images, we seamlessly reframe perception as image generation. Our generalist model, Vision Banana, achieves SOTA results on a variety of vision tasks involving both 2D and 3D understanding, beating or rivaling zero-shot domain-specialists, including Segment Anything Model 3 on segmentation tasks, and the Depth Anything series on metric depth estimation. We show that these results can be achieved with lightweight instruction-tuning without sacrificing the base model's image generation capabilities. The superior results suggest that image generation pretraining is a generalist vision learner. It also shows that image generation serves as a unified and universal interface for vision tasks, similar to text generation's role in language understanding and reasoning. We could be witnessing a major paradigm shift for computer vision, where generative vision pretraining takes a central role in building Foundational Vision Models for both generation and understanding.
 ICLRTop 12%
Grammar of the Wave: Towards Explainable Multivariate Time Series Event Detection via Neuro-Symbolic VLM Agents
Time Series Event Detection (TSED) aims to localize semantically meaningful events in time series data, with critical applications in high-stakes domains. Unlike statistical anomalies, events are often defined by natural-language descriptions with internal temporal-logic structures across multiple physical channels. However, in real-world settings, dense event annotations are expensive to obtain, making purely supervised learning difficult. We introduce Language-guided TSED, a setting where a model is given textual event descriptions and must ground them to intervals in multivariate signals with little or no labeled data. To address this problem, we propose Event Logic Tree (ELT), a knowledge representation framework that converts linguistic descriptions into structured temporal logic over signal primitives. Building on ELT, we present SELA, a neuro-symbolic VLM agent framework that iteratively grounds primitives from signal visualizations and composes them under ELT constraints, producing both event intervals and faithful tree-structured explanations. We further release a real-world benchmark across energy and climate domains with expert knowledge and annotations. Experiments show that SELA improves over supervised fine-tuning and existing zero/few-shot time series reasoning baselines.
SkillOpt: Executive Strategy for Self-Evolving Agent Skills
Agent skills today are hand-crafted, generated one-shot, or evolved through loosely controlled self-revision, none of which behaves like a deep-learning optimizer for the skill, and none of which reliably improves over its starting point under feedback. We argue the skill should instead be trained as the external state of a frozen agent, with the same discipline that makes weight-space optimization reproducible. SkillOpt is, to our knowledge, the first systematic controllable text-space optimizer for agent skills: a separate optimizer model turns scored rollouts into bounded add/delete/replace edits on a single skill document, and an edit is accepted only when it strictly improves a held-out validation score. A textual learning-rate budget, rejected-edit buffer, and epoch-wise slow/meta update make skill training stable while adding zero inference-time model calls at deployment. Across six benchmarks, seven target models, and three execution harnesses (direct chat, Codex, Claude Code), SkillOpt is best or tied on all 52 evaluated (model, benchmark, harness) cells and beats every per-cell competitor among human, one-shot LLM, Trace2Skill, TextGrad, GEPA, and EvoSkill skills. On GPT-5.5 it lifts the average no-skill accuracy by +23.5 points in direct chat, by +24.8 inside the Codex agentic loop, and by +19.1 inside Claude Code. Transfer experiments further show that optimized skill artifacts retain value when moved across model scales, between Codex and Claude Code execution environments, and to a nearby math benchmark without further optimization.
 SIGIRTop 19%
Experts First, Iteration Second: Auditable Self-Improvement for Scientific Peer-Review Agents
Self-improving agents are often framed as recursive systems that discover their own improvement procedures. For high-stakes vertical NLP systems, however, the bottleneck is often not autonomy but the placement of expert knowledge: domain specialists can supply rubrics, failure modes, calibration examples, and deployment constraints that an open search loop would otherwise need to rediscover. We present SIRA (self-improving review agent), an expert-bootstrapped agent factory for scientific peer-review support. SIRA keeps the online reviewer and common execution harness fixed, while offline iterations edit only venue-specific artifacts: rubrics, metadata, prompts, templates, calibration rules, benchmark packs, and failure analyses. On a paper-review agent-creation task, SIRA achieves a mean best held-out decision-label accuracy of 0.941 over five runs, compared with 0.865 for a HyperAgents-style open editable-agent baseline under the same dataset split and metric; it also reaches its best candidate in roughly one third as many scored steps. The claim is bounded but sharp: in peer-review support, self-improvement can be strongest when experts shape the search space first and iteration is restricted to auditable, versioned factory artifacts.
Accelerating scientific discovery with Co-Scientist
Scientific discovery is driven by scientists generating novel hypotheses for complex problems that undergo rigorous experimental validation. To augment this process, we introduce Co-Scientist, a multi-agent AI system built on Gemini for structured scientific thinking and hypothesis generation. Co-Scientist aims to help scientists discover new original knowledge. Conditioned on their research objectives and prior scientific evidence, it formulates demonstrably novel research hypotheses for experimental verification. The system’s design involves agents continuously generating, critiquing and refining hypotheses accelerated by scaling test-time compute. Key contributions include: (1) a multi-agent architecture with an asynchronous task execution framework for flexible compute scaling; (2) a tournament evolution process for self-improving hypotheses generation. Automated evaluations show continued benefits of test-time compute scaling, improving hypothesis quality over time. While general purpose, we focus the validation in three biomedical applications: drug repurposing, novel target discovery 1, and explaining mechanisms of anti-microbial resistance 2. Specifically, Co-Scientist helped identify new drug repurposing candidates and synergistic combination therapies for acute myeloid leukemia, which were validated through in vitro experiments. These real-world validations demonstrate the potential of Co-Scientist to accelerate scientific discovery and usher in an era of AI empowered scientists.
Agent Should Invoke External Tools ONLY When Epistemically Necessary
As large language models evolve into tool-augmented agents, a central question remains unresolved: when is external tool use actually justified? Existing agent frameworks typically treat tools as ordinary actions and optimize for task success or reward, offering little principled distinction between epistemically necessary interaction and unnecessary delegation. This position paper argues that agents should invoke external tools only when epistemically necessary. Here, epistemic necessity means that a task cannot be completed reliably via the agent's internal reasoning over its current context, without any external interaction. We introduce the Theory of Agent (ToA), a framework that treats agents as making sequential decisions about whether remaining uncertainty should be resolved internally or delegated externally. From this perspective, common agent failure modes (e.g., overthinking and overacting) arise from miscalibrated decisions under uncertainty rather than deficiencies in reasoning or tool execution alone. We further discuss implications for training, evaluation, and agent design, highlighting that unnecessary delegation not only causes inefficiency but can impede the development of internal reasoning capability. Our position provides a normative criterion for tool use that complements existing decision-theoretic models and is essential for building agents that are not only correct, but increasingly intelligent.
On the limits and opportunities of AI reviewers: Reviewing the reviews of Nature-family papers with 45 expert scientists
With the advancement of AI capabilities, AI reviewers are beginning to be deployed in scientific peer review, yet their capability and credibility remain in question: many scientists simply view them as probabilistic systems without the expertise to evaluate research, while other researchers are more optimistic about their readiness without concrete evidence. Understanding what AI reviewers do well, where they fall short, and what challenges remain is essential. However, existing evaluations of AI reviewers have focused on whether their verdicts match human verdicts (e.g., score alignment, acceptance prediction), which is insufficient to characterize their capabilities and limits. In this paper, we close this gap through a large-scale expert annotation study, in which 45 domain scientists in Physical, Biological, and Health Sciences spent 469 hours rating 2,960 individual criticisms (each targeting one specific aspect of a paper) from human-written and AI-generated reviews of 82 Nature-family papers on correctness, significance, and sufficiency of evidence. On a composite of all three dimensions, a reviewing agent powered by GPT-5.2 scores above each paper's top-rated human reviewer (60.0% vs. 48.2%, p = 0.009), while all three AI reviewers (including Gemini 3.0 Pro and Claude Opus 4.5) exceed the lowest-rated human across every dimension. AI reviewers' accurate criticisms are also more often rated significant and well-evidenced, and surface a distinct 26% of issues no human raises. However, AI reviewers overlap far more than humans do (21% vs. 3% for cross-reviewer pairs), and exhibit 16 recurring weaknesses humans do not share, such as limited subfield knowledge, lack of long context management over multiple files, and overly critical stance on minor issues. Overall, our results position current AI reviewers as complements to, not substitutes for, human reviewers.
Neural Computers
We propose a new frontier: Neural Computers (NCs) that unify computation, memory, and I/O of traditional computers in a learned runtime state. Our long-term goal is the Completely Neural Computer (CNC): the mature, general-purpose realization of this emerging machine form, with stable execution, explicit reprogramming, and durable capability reuse. As an initial step, we study whether elementary NC primitives can be learned solely from collected I/O traces, without instrumented program state. Concretely, we instantiate NCs as video models that roll out screen frames from instructions, pixels, and user actions (when available) in CLI and GUI settings. We show that NCs can acquire elementary interface primitives, especially I/O alignment and short-horizon control, while routine reuse, controlled updates, and symbolic stability remain challenging. We outline a roadmap toward CNCs, to establish a new computing paradigm beyond today's agents and conventional computers.
Continuous Latent Diffusion Language Model
Large language models have achieved remarkable success under the autoregressive paradigm, yet high-quality text generation need not be tied to a fixed left-to-right order. Existing alternatives still struggle to jointly achieve generation efficiency, scalable representation learning, and effective global semantic modeling. We propose Cola DLM, a hierarchical latent diffusion language model that frames text generation through hierarchical information decomposition. Cola DLM first learns a stable text-to-latent mapping with a Text VAE, then models a global semantic prior in continuous latent space with a block-causal DiT, and finally generates text through conditional decoding. From a unified Markov-path perspective, its diffusion process performs latent prior transport rather than token-level observation recovery, thereby separating global semantic organization from local textual realization. This design yields a more flexible non-autoregressive inductive bias, supports semantic compression and prior fitting in continuous space, and naturally extends to other continuous modalities. Through experiments spanning 4 research questions, 8 benchmarks, strictly matched ~2B-parameter autoregressive and LLaDA baselines, and scaling curves up to about 2000 EFLOPs, we identify an effective overall configuration of Cola DLM and verify its strong scaling behavior for text generation. Taken together, the results establish hierarchical continuous latent prior modeling as a principled alternative to strictly token-level language modeling, where generation quality and scaling behavior may better reflect model capability than likelihood, while also suggesting a concrete path toward unified modeling across discrete text and continuous modalities.
ELF: Embedded Language Flows
Diffusion and flow-based models have become the de facto approaches for generating continuous data, e.g., in domains such as images and videos. Their success has attracted growing interest in applying them to language modeling. Unlike their image-domain counterparts, today's leading diffusion language models (DLMs) primarily operate over discrete tokens. In this paper, we show that continuous DLMs can be made effective with minimal adaptation to the discrete domain. We propose Embedded Language Flows (ELF), a class of diffusion models in continuous embedding space based on continuous-time Flow Matching. Unlike existing DLMs, ELF predominantly stays within the continuous embedding space until the final time step, where it maps to discrete tokens using a shared-weight network. This formulation makes it straightforward to adapt established techniques from image-domain diffusion models, e.g., classifier-free guidance (CFG). Experiments show that ELF substantially outperforms leading discrete and continuous DLMs, achieving better generation quality with fewer sampling steps. These results suggest that ELF offers a promising path toward effective continuous DLMs.